GPT Image 2
OpenAI's natively multimodal image model — the default engine behind Face / Identity.
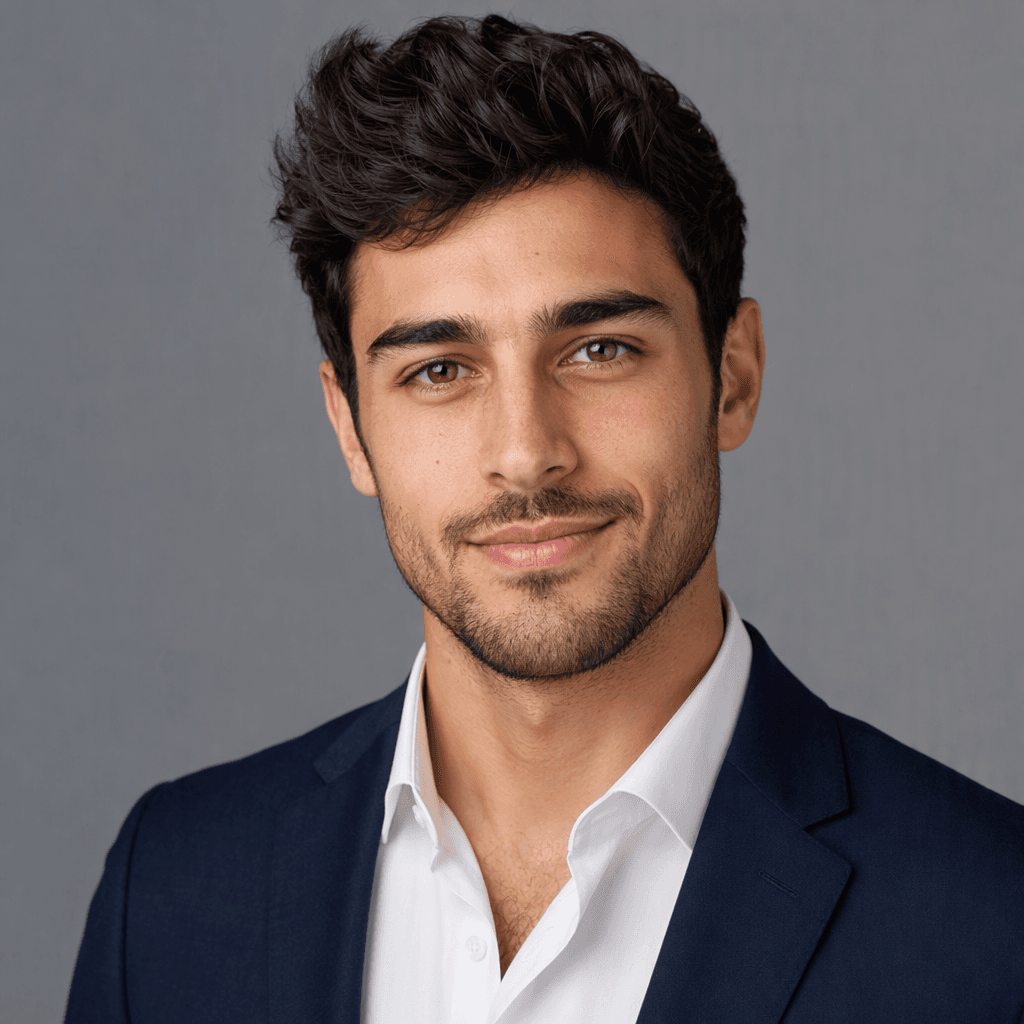
What GPT Image 2 does
GPT Image 2 turns a text prompt, an existing photo, or a reference image into a new image — a portrait, a product shot, a scene — while following detailed instructions about composition, style, and text placement.
On AutorunX it's the default model behind Face / Identity: generating consistent, on-brand photos of an AI persona from a short prompt and a reference face, so the same identity can be reused across a shoot.
Capabilities
Key features
- Strong multi-constraint instruction-following
- Because it's built on the same architecture as GPT rather than a bolted-on diffusion pipeline, GPT Image 2 tends to hold onto every constraint in a dense prompt — exact pose, specific object count, precise text placement — where diffusion-only models start dropping details as prompts get longer.
- Reference-guided identity consistency
- Feed it one or more reference images — a face, a product, a brand's visual style — and it anchors new generations to that reference, which is exactly what a reusable Face / Identity persona needs across a full photoshoot.
- Reliable in-image text rendering
- Logos, signage, captions, and other in-scene text render legibly far more often than on most diffusion-based image models, which is useful for banner ads and product shots that need real, readable copy inside the frame.
- Image-to-image transformation
- Start from an existing photo and transform it — change the setting, outfit, or style — while preserving the underlying subject, rather than generating from a blank prompt every time.
- Up to 4K-capable output
- Resolution scales up to a 4K-capable tier, giving room to move between fast preview generations and a final high-resolution export.
How GPT Image 2 works
GPT Image 2 generates images token-by-token inside the same multimodal architecture OpenAI uses for GPT itself, rather than running a separate diffusion model behind a text encoder. That native integration is what gives it strong instruction-following — dense prompts with multiple constraints (text overlays, specific poses, exact object counts) tend to hold up better than on diffusion-only models.
It supports three modes: text-to-image generation from a written prompt, image-to-image transformation of an existing photo, and reference-guided generation, where one or more reference images (e.g. a person's face, a product, a brand style) anchor the output so the result stays consistent with the source.
Output resolution scales up to a 4K-capable tier, and the model can render legible text inside an image — logos, signage, captions — more reliably than most diffusion-based competitors.
What people use GPT Image 2 for
Face / Identity persona photos
Generate a consistent set of photos for an AI persona — different poses, outfits, and settings — all anchored to the same reference face for a coherent identity across a shoot.
Product photography
Turn a plain product photo into a styled shot in a new setting or lighting scenario, keeping the product itself accurate and unchanged.
Banner and ad creative with real text
Generate marketing images with legible in-scene text — headlines, calls-to-action, logos — instead of adding text as a separate overlay after generation.
Social content variations
Produce multiple on-brand variations of the same shot for different platforms or campaigns without re-shooting.
How to use GPT Image 2 on AutorunX
GPT Image 2 is the default model for Character, in the Image module.
- 01
Open Face / Identity in Image
From the AutorunX dashboard, go to Image → Face / Identity. This is the panel for generating and managing a consistent AI persona.
- 02
Set your identity reference
Upload or select a reference face/angle set so generations stay consistent with the same persona across shots.
- 03
Pick GPT Image 2 in the model picker
GPT Image 2 is the default model for Face / Identity. Open the model picker to confirm it's selected, or compare it against other image models by rate.
- 04
Prompt and generate
Describe the shot — pose, setting, outfit, framing — and generate. Save the frames you like back to the persona's angle rail for reuse.
- Billed per generated image from your shared AutorunX credit wallet.
- 48 credits / image
Tips for better results
- Give it one clean reference face
- For consistent Face / Identity output, use a single clear, well-lit reference image rather than several conflicting angles — the model anchors more reliably to one strong reference.
- Be explicit about every constraint
- GPT Image 2 rewards specificity — describe pose, lighting, framing, and any in-image text exactly. Vague prompts leave more to chance than they would on a purely stylistic diffusion model.
- Use image-to-image for incremental changes
- If a generation is close but not right, feed it back in as the input image and describe the specific change, instead of rewriting the prompt from scratch.
- Save good frames back to the persona rail
- On AutorunX, save frames you like back to the Face / Identity's angle rail so future generations for the same persona have more reference material to stay consistent against.
GPT Image 2 — frequently asked
Related models
Veo 3.1
Google DeepMindGoogle's flagship text-to-video and image-to-video model with native synced audio.
Nano Banana
Google DeepMindGoogle's Gemini-family image model, nicknamed Nano Banana for its viral photorealistic edits, generates and edits images up to a 4K-capable tier.
Seedream
ByteDance / BytePlusByteDance's Seedream generates and edits images from up to ten reference photos, holding identity and composition steady across a full shoot.
Ready to create with GPT Image 2?
Open Character and generate your first image in a couple of minutes.
Free plan, no card required.